RTX 5080 vs 4090 for AI: Which GPU Fits Your Workload?
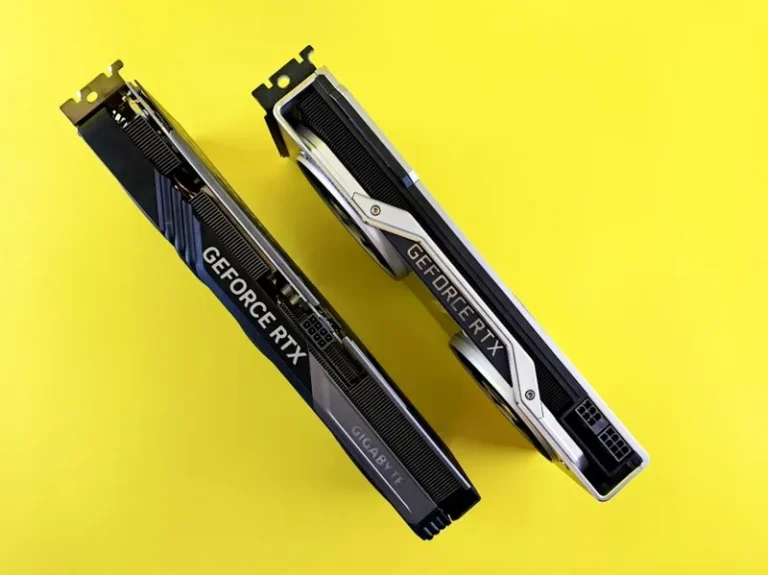
The question of RTX 5080 vs 4090 for AI work is increasingly common as local large language models and image generation move into the mainstream. Both cards are serious AI accelerators, but they serve different people, and the “newer is better” instinct will mislead you here. The RTX 4090 carries 24 GB of VRAM against the 5080’s 16 GB, and in AI work, VRAM is almost always the deciding factor rather than raw shader speed. If you are choosing a GPU for fine-tuning, running larger models, or generating images at scale, the older 4090 often wins despite being a generation behind in gaming features.
That said, the 5080 is not a bad AI card, and at roughly half the price it offers compelling value for smaller models. The right answer depends on exactly what you plan to run, which is what this comparison unpacks in detail.
RTX 5080 vs 4090 for AI: Specs That Actually Matter
For AI, the gaming-facing spec sheet matters less than VRAM capacity and memory bandwidth, because both determine how large a model you can load and how fast tokens stream. Here is the head-to-head on the numbers that count.
| Specification | RTX 5080 | RTX 4090 |
|---|---|---|
| VRAM | 16 GB GDDR7 | 24 GB GDDR6X |
| Memory bandwidth | 960 GB/s | 1,008 GB/s |
| CUDA cores | 10,752 | 16,384 |
| Tensor cores | 5th-gen (more per core) | 4th-gen |
| TDP | 360 W | 450 W |
| Typical 2026 price | $999–$1,099 | $1,900–$2,200 |
| Max model size (fp16) | ~13B comfortably | ~20B+ comfortably |
The memory bandwidth is closer than you might expect, because GDDR7 runs faster per pin than GDDR6X. But the raw 24 GB versus 16 GB difference is what dominates real-world AI use, and it is not close.
VRAM Is the Whole Game in AI
Everything in local AI revolves around how much model you can fit in memory. A 24 GB card can load and run a 20-billion-parameter model without aggressive quantization, while a 16 GB card tops out comfortably around 13 billion parameters. That difference determines which models you can even attempt.
It matters even more for fine-tuning, where activations and gradients add significant overhead beyond the base model weights. The RTX 4090’s 24 GB buffer is the practical entry point for fine-tuning smaller LLMs at home, while the 5080 will hit the ceiling quickly on the same task. If you do any serious model work, this is the single reason the older card still commands a premium.
Inference Speed: How They Compare
For pure inference at a given model size, the two cards are closer than the spec gap suggests. The RTX 5080’s fifth-generation tensor cores and newer architecture help it punch above its VRAM weight, and in throughput tests on small models that fit both cards, it can match or even edge out the 4090 in tokens per second per watt.
However, “fit” is doing the heavy lifting there. Once you run a model that only the 4090 can hold comfortably, the comparison stops being close, because the 5080 must either quantize harder or run the model across system RAM at a fraction of the speed. The RTX 5080 vs 4090 for AI debate, in other words, is really a question of whether your target models fit in 16 GB.
Image Generation and Diffusion Models
For Stable Diffusion and similar diffusion models, both cards are strong, and the 5080’s newer tensor cores give it a genuine edge in raw generation speed per image. If you are generating images at 512 to 1024 resolution for personal or freelance work, the 5080 is often the faster card per dollar.
The turning point is high-resolution or batch generation, where larger diffusion models and higher resolutions can push past 16 GB of VRAM. For stable diffusion upscaling, ControlNet pipelines, or video generation models, the 4090’s 24 GB becomes the more comfortable choice again. This pattern repeats across every AI workload: the 5080 wins on speed and value until VRAM becomes the limit.
Price and the Value Question
The RTX 5080 vs 4090 for AI comparison gets complicated on price because you are buying two different things. The 5080 at around $1,000 is a modern gaming card that happens to be a capable AI tool. The 4090 at $1,900 to $2,200 is, in 2026, effectively a discounted home AI workstation card, its price inflated by its 24 GB of VRAM.
If your AI work is casual, such as experimenting with 7B to 13B models or occasional image generation, buy the 5080 and keep the extra $1,000. If you are serious about running larger models, fine-tuning, or batch generation, the 4090’s VRAM is worth the premium, and it is still far cheaper than a proper 48 GB workstation card.
Which Should You Choose?
Choose the RTX 5080 if your AI ambitions fit inside 16 GB: 13B-parameter models and smaller, Stable Diffusion at standard sizes, or AI-assisted coding and occasional experimentation. It is faster per watt, newer, and dramatically better value.
Choose the RTX 4090 if you need 24 GB for a 20B-plus model, fine-tuning, LoRA training, or high-resolution and video generation that blows past 16 GB. For that user, the older card is not a compromise but the cheapest way into serious local AI. For a related look at NVIDIA’s flagships in gaming rather than AI, see my rtx 5080 vs 4090 comparison and my best graphics card for gaming 2026 roundup.
Software and Ecosystem Considerations
Beyond raw hardware, the software story tips the RTX 5080 vs 4090 for AI comparison further toward the newer card for casual users. The RTX 5080 ships with the newest generation of Nvidia’s CUDA and TensorRT stack fully supported from day one, and its media encoders are faster for a generation. Driver support for the newer Blacksmith architecture, however, is still maturing in niche AI frameworks, while the RTX 4090 benefits from three years of optimization across every major library.
In practice, this is a modest factor for most people. Popular tools like PyTorch, llama.cpp, and the leading diffusion front-ends run well on both cards, and the gap closes with each driver release. It is only worth weighing if you depend on a less-common framework that lags on newer hardware. For the vast majority of AI tinkerers, VRAM capacity remains a far more decisive factor than any software quirk.
FAQ
Is the RTX 4090 better than the 5080 for AI?
For large models and fine-tuning, yes, because of its 24 GB of VRAM versus the 5080’s 16 GB. For smaller models that fit both cards, the 5080 is competitive or faster per watt, and it costs roughly half as much as the 4090.
Can the RTX 5080 run AI models?
Absolutely. It runs 7B to 13B-parameter models comfortably and handles image generation well. It only becomes limited when a model’s memory footprint exceeds 16 GB.
How much VRAM do I need for local AI?
For experimentation, 16 GB is a reasonable starting point. For larger LLMs, fine-tuning, or high-resolution generation, 24 GB is far more comfortable and unlocks a wider range of models.
Is the RTX 4090 still worth buying in 2026 for AI?
Yes, for AI specifically. Its 24 GB of VRAM keeps it relevant as a home AI accelerator even though it has been replaced in NVIDIA’s gaming lineup by the 50-series.
Which GPU is best for Stable Diffusion?
Both are excellent. The 5080 is often faster per dollar for standard image sizes, while the 4090 is better for high-resolution, batch, and video generation that exceeds 16 GB of VRAM.
Conclusion
The RTX 5080 vs 4090 for AI decision comes down to VRAM. If your models fit in 16 GB, the RTX 5080 is the smarter buy: newer, more efficient, and around half the price. If you need 24 GB for larger language models, fine-tuning, or high-resolution generation, the RTX 4090 remains the best value entry into serious local AI, discontinued or not.
Before you commit, confirm your target models’ memory footprints and check independent benchmarks at Tom’s Hardware and the official specifications on Nvidia’s GeForce page. For full-system budgeting, my how much does it cost to build a gaming pc guide also applies to AI-focused builds.